Prompt Versioning and A/B Testing — iterate with data
Track prompt changes, run controlled A/B tests against evaluation datasets, and deploy the best-performing version with confidence.
Optimization4.4
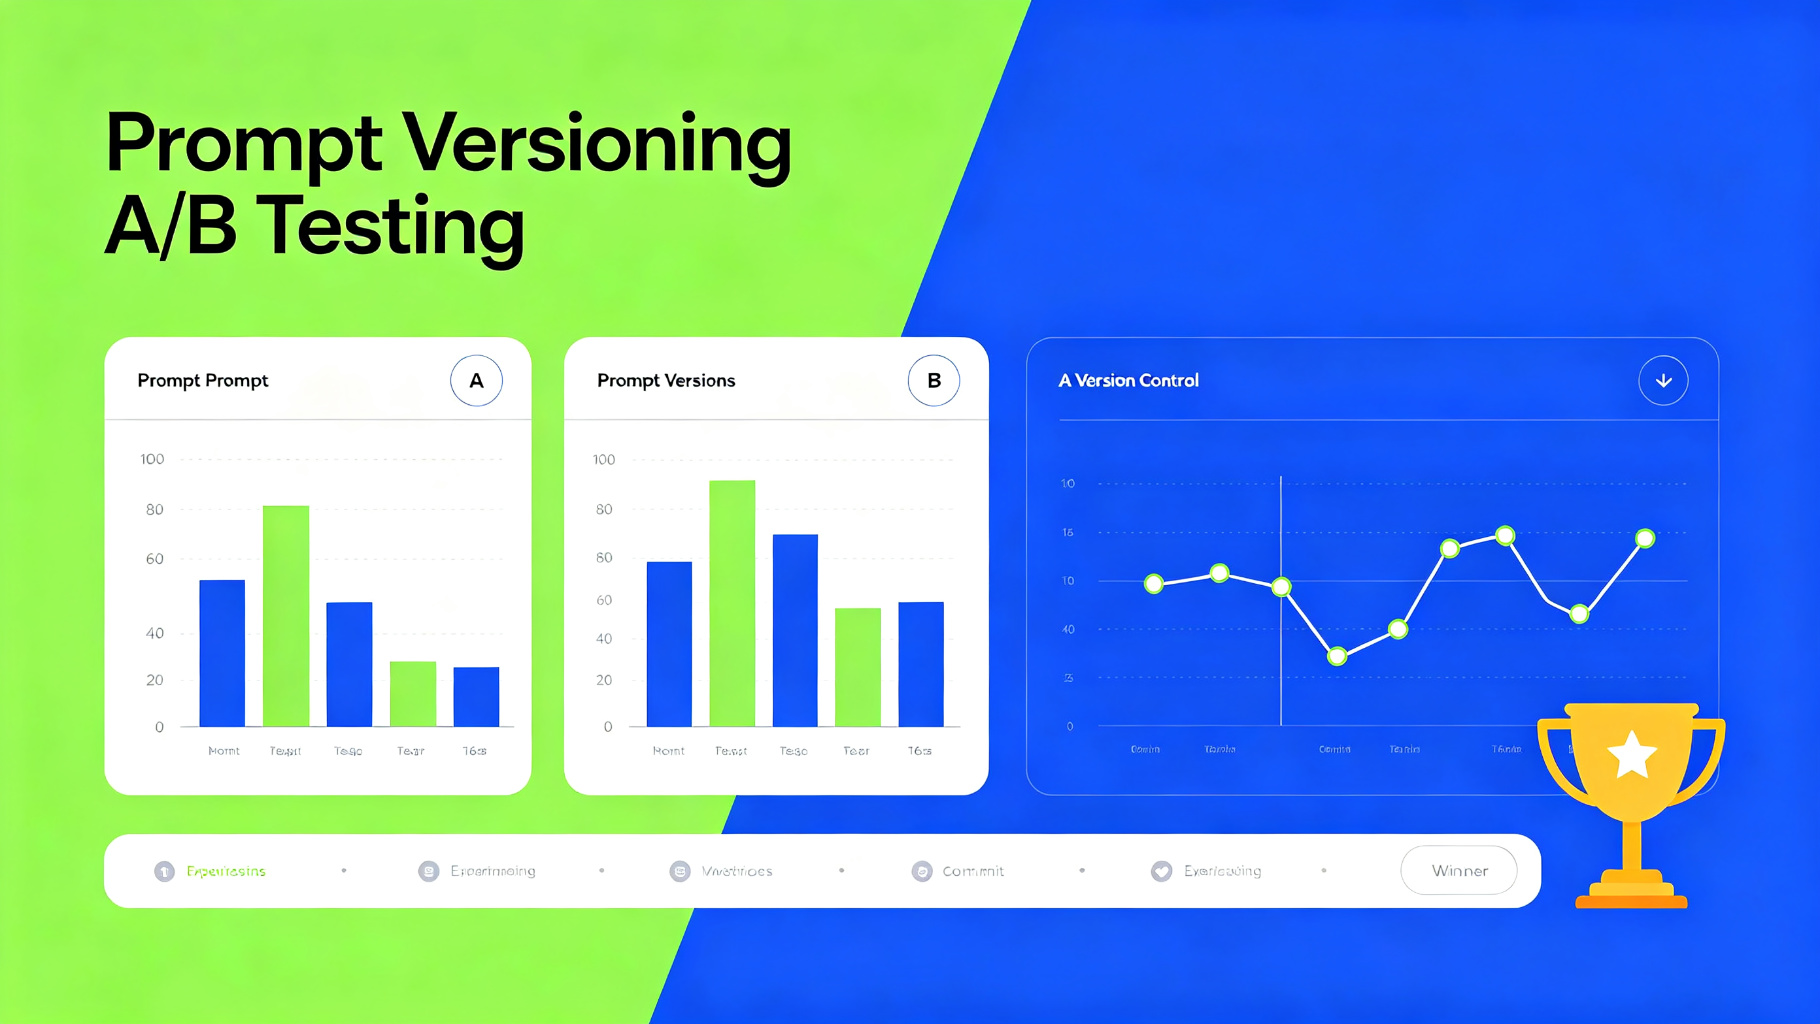
Prompt template
Evaluate this prompt version against the test set.

Prompt: {prompt_version}
Test cases: {evaluation_dataset}

For each test case, score output on:
- Accuracy (1-5)
- Relevance (1-5)
- Format compliance (1-5)

Report average scores and identify failing cases.How to use
- 1Create a versioned prompt registry (Git or prompt management tool)
- 2Build an evaluation dataset of 20-50 representative test cases
- 3Define scoring rubrics for each quality dimension
- 4Run A/B tests with statistical significance (p<0.05)
- 5Deploy winning version and archive the old one
Pro tips
- Use tools like PromptFoo, LangSmith, or Humanloop for evaluation
- Test with edge cases and adversarial inputs, not just happy paths
- Run at least 30 samples per version for statistical significance
- Document what changed and why in each version
A/B TestingVersioningEvaluationMLOpschatgpt
Ratings & Reviews
Loading reviews…
Related Skills
Optimization
Context Window Management — fit more without losing quality
Use summarization, compression, selective retrieval, and sliding windows to manage long context without exceeding limits or losing key information.
Context WindowSummarizationCompression
4.1
Evaluation
LLM-as-Judge — automate evaluation with AI scoring
Use a strong LLM to score model outputs against rubrics, compare A/B variants, and generate qualitative feedback at scale without human annotators.
EvaluationLLM-as-JudgeScoring
4.7
Prompting
Multi-Modal Prompting — combine text, images, and audio in one prompt
Structure prompts that include images, audio, and text together, with clear instructions on how each modality should be used.
Multi-ModalVisionAudio
4.4